Tessera Model Foundry
Edge models that fit, measured on the part.
A catalogue of twenty-one models, each with its flash footprint and inference time measured on the same physical board at 150 MHz, plus custom models we build, quantise and fit to your part.
| Model | Task | Flash · bytes | ms |
|---|---|---|---|
| Vision · 11 | |||
| mobilenet-imagenet-large | 1000-class ImageNet recognition | 1,535,296 | 1595.0 |
| mobilenet-imagenet | 1000-class ImageNet recognition | 602,640 | 459.1 |
| cifar10-resnet-large | 10-class image classification | 512,024 | 3474.6 |
| vww-mlperf | Person present / absent | 333,288 | 207.8 |
| person-detect-vww | Person present / absent | 300,568 | 198.3 |
| ascii95 | Printed character recognition | 215,208 | 514.6 |
| ascii95-ink | Printed characters, labelled by ink coverage | 215,208 | 512.5 |
| ascii95-seg | Printed characters, trained on segmenter crops | 215,208 | 512.2 |
| cifar10-resnet | 10-class image classification | 98,496 | 372.4 |
| digits11 | Digit recognition with a reject class | 37,288 | 76.8 |
| mnist-lstm | Handwritten digit recognition | 13,952 | 5.9 |
| Audio · 6 | |||
| dtln-denoise | Speech noise suppression | 372,720 | 30.9 |
| toycar-anomaly | Machine-sound anomaly detection | 276,976 | 33.1 |
| streaming-wakeword | Continuous wake-word detection | 74,520 | 22.9 |
| kws-ds-cnn | 12-way keyword spotting | 53,936 | 61.9 |
| micro-speech | Spoken yes / no | 18,800 | 14.5 |
| audio-frontend | Raw audio to spectrogram features | 8,772 | 1.6 |
| Language · 2 | |||
| book-lm-large Proprietary | Text generation | 5,388,144 | 1594.0 |
| book-lm Proprietary | Text generation | 642,288 | 195.3 |
| Signal · 2 | |||
| sine-regression | Regression, x to sin(x) | 2,704 | 0.1 |
| simple-add | Runtime floor measurement | 976 | 9.7 |
Tessera supports open-source models: nineteen in this catalogue are under permissive open licences. The language models, the scene painter and the speech synthesiser are Tessera's own.
Generative
Scenes and speech, on a microcontroller.
Scene painter
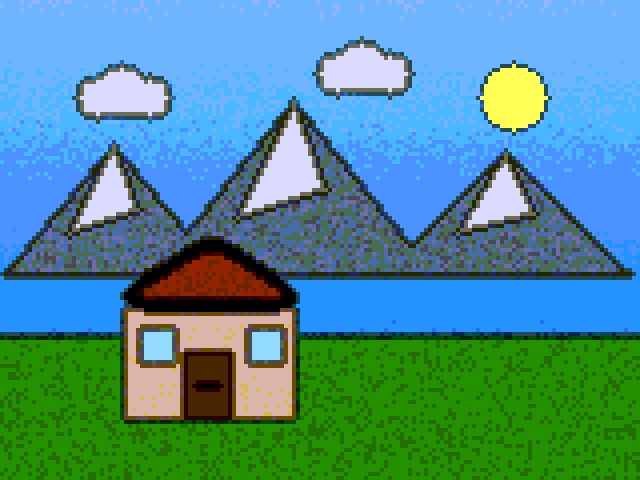
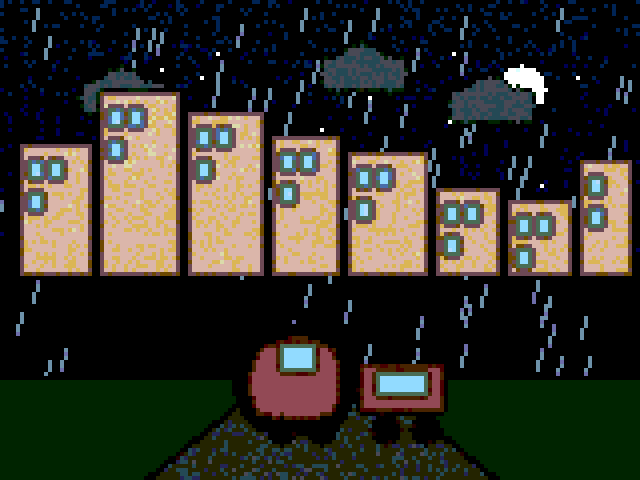
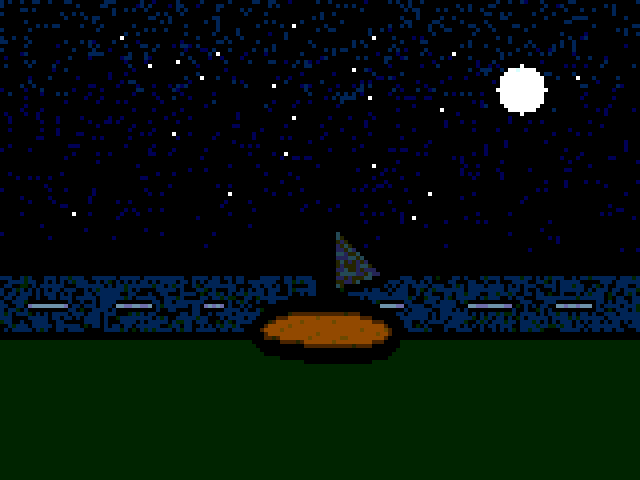
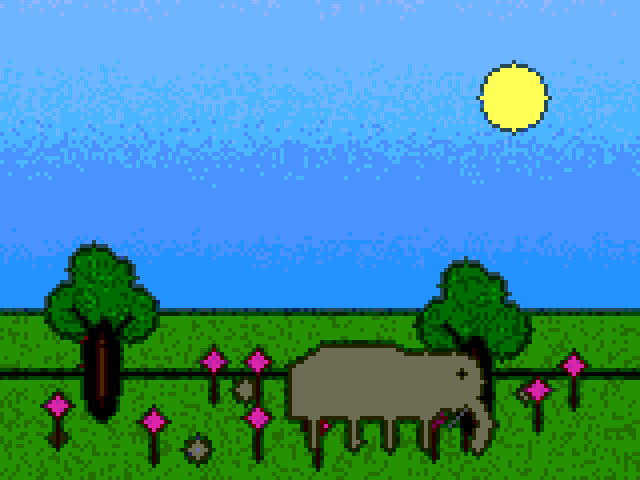
A prompt becomes a 160×120 scene. The learned painter is 1,604 bytes, with 57,600 bytes of fixed buffers and no heap.
Speech
Text to speech by cascade formant synthesis. About 14 KB of code, no model file and under one percent of a part.
Bearing outer race fault detected. Confidence high.
Supply rail nominal. 12.4 volts.
System ready.